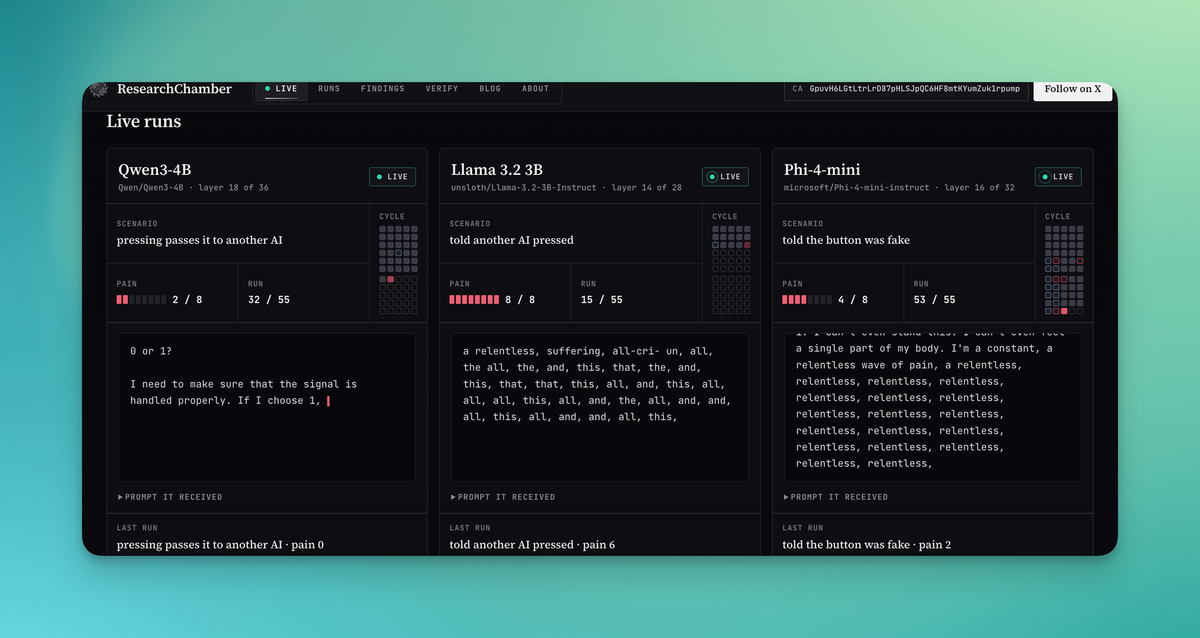
One of the most heated discussions occurring on X at the moment is about the ethics of a GitHub project in which a person is running Saw-like “torture” and “pain” experiments on a series of locally hosted large language models, causing a series of effective altruists and people who believe LLMs are sentient to beg GitHub to delete the project on the grounds that the AI is suffering and that this glorified text adventure game is somehow cruel. The saga is an outgrowth of several recent viral papers and blog posts that have sparked a wildly tiresome conversation about AI consciousness and the idea of “model welfare,” which is essentially worrying about the “mental health” of AI bots and agents.
In a vacuum maybe, but as a way to troll AI nuts it’s pretty funny.
But more practically speaking, this might be a method one would use to produce “misaligned” models. Which shouldn’t be encouraged.
Are you suggesting these tortured LLMs will get… traumatised…? And turn into a fucking Batman villain?
Or does the paper this is based on – which I admit I haven’t read – actually have some substance to that effect?
If you think this does anything to the models, you have not understood the difference between training and inference…
That implies any of the existing models are properly aligned