Ah yes, because even a single fucking percent of people that use an interpreter or compiler understand how they work, let alone can create one, or validate their output.
Have you heard of open weight models, or are you just willfully ignorant?
OMG, yes! Why didn’t I think of that before!? I’m gonna be a psychology doctor and rename all my hallucinating patients as “Claude” and BAM! They become genius now!
Local models are still controlled by a small group of people, in the sense of deciding how and with what to train the thing. And given the cost of doing so, you can’t just easily fork it and make adjustments yourself.
How about going SETI@home with LLM training? Everyone contributing their own computing power to train better, more transparent local models. Using properly licensed, publically available datasets. Not sure how viable this approach would be, but that would make forking of open-source models possible, maybe?
Olmo exposes all of its training code and training data, including post-training etc.
I’ve trained a tiny GPT model on my computer before. It’s shitty, certainly, very shitty actually, but essentially anyone can train an LLM, if you got either enough time or calculation power.
using proprietary tech whose purpose is to hook you and then enshittify after you become reliant on it
(Opens trenchcoat in alley)
“Psst… Hey guy…ya want uncanny waifu images? Ya wanna code faster? Ya wanna write your own kernel? Make a game without thinking too hard? Heh heh…first thousand tokens are free, buddy. Heh heh heh. (Wink)”

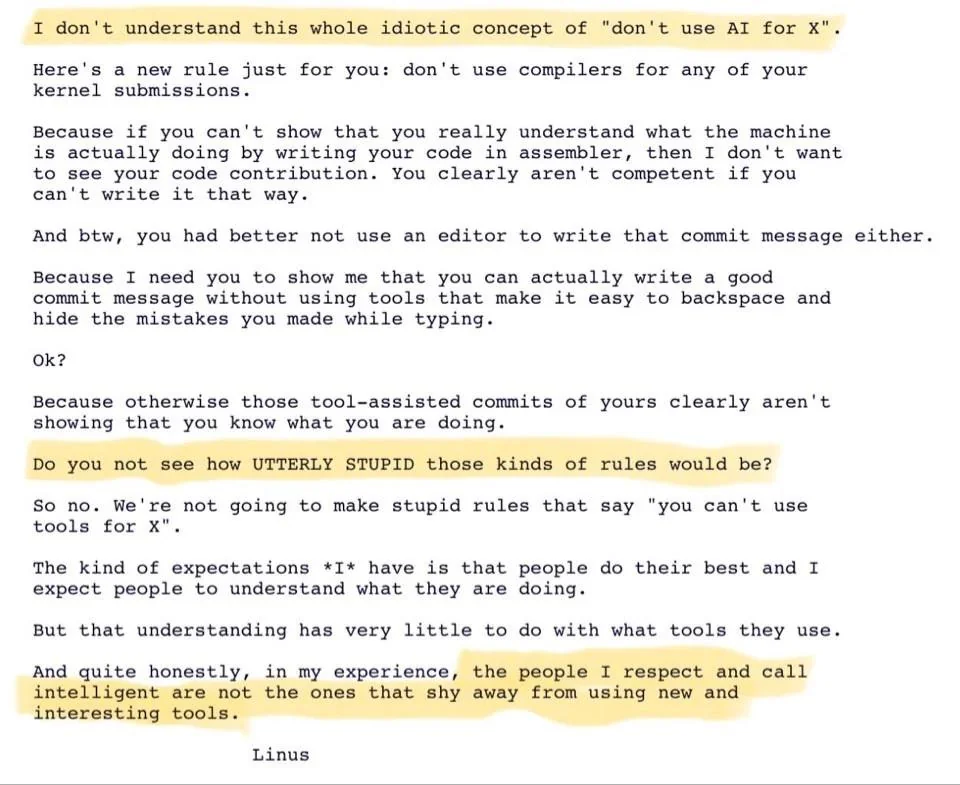
hes comparing knowing how open concepts work vs using proprietary tech whose purpose is to hook you and then enshittify after you become reliant on it
Ah yes, because even a single fucking percent of people that use an interpreter or compiler understand how they work, let alone can create one, or validate their output.
Have you heard of open weight models, or are you just willfully ignorant?
but local models exist, they are a direct threat to anthropic/OpenAi/Xai thats why we must invest our time to make proprietary models irrelevant.
Except Linus is using Claude.
OMG, yes! Why didn’t I think of that before!? I’m gonna be a psychology doctor and rename all my hallucinating patients as “Claude” and BAM! They become genius now!
Local models are still controlled by a small group of people, in the sense of deciding how and with what to train the thing. And given the cost of doing so, you can’t just easily fork it and make adjustments yourself.
How about going SETI@home with LLM training? Everyone contributing their own computing power to train better, more transparent local models. Using properly licensed, publically available datasets. Not sure how viable this approach would be, but that would make forking of open-source models possible, maybe?
Olmo exposes all of its training code and training data, including post-training etc.
Olmo: https://huggingface.co/allenai/Olmo-3-1125-32B
Also Apertus: https://www.apertus-ai.org/
I’ve trained a tiny GPT model on my computer before. It’s shitty, certainly, very shitty actually, but essentially anyone can train an LLM, if you got either enough time or calculation power.
Which is very different from compilers, especially for large languages with existing open source code. Those you just change willy nilly, as you want.
(Opens trenchcoat in alley) “Psst… Hey guy…ya want uncanny waifu images? Ya wanna code faster? Ya wanna write your own kernel? Make a game without thinking too hard? Heh heh…first thousand tokens are free, buddy. Heh heh heh. (Wink)”